What's it like being a container? Part 3
Cgroups, veth, iptables NAT and OverlayFS, the final pieces of how a container actually runs.
Published 17th May, 2026
Part 1 covered PID namespaces and why PID 1 matters. Part 2 covered the other namespaces, UTS, IPC, Mount, and User. This one closes it out with cgroups, networking, and the filesystem layer that makes images actually work.
cgroups
Namespaces control what a process can see. cgroups, control groups, control how much of the host’s resources it can use. Without them, a single container could spike to 100% CPU or exhaust all available memory and bring down everything else on the host. Docker maps each container to a cgroup hierarchy you can look at directly:
$> ls /sys/fs/cgroup/system.slice/docker-<container-id>.scope/
cgroup.controllers  cpu.max  cpu.stat  memory.current  memory.max ...
When you start a container with limits, Docker writes to those files:
$> docker run -d --memory="256m" --cpus="0.5" --name nginx nginxUnder the hood, that translates to something like:
echo 268435456 > /sys/fs/cgroup/.../memory.max
echo "50000 100000" > /sys/fs/cgroup/.../cpu.max
The cpu.max value is a quota/period pair, the container gets 50ms of CPU time for every 100ms window. That’s half a core regardless of what else is running.
One thing worth knowing: if a container hits its memory limit, the kernel’s OOM killer steps in and kills processes inside it. You’ll see this as exit code 137 in docker inspect (128 + SIGKILL):
$> docker inspect nginx | grep -i oomkilled
"OOMKilled": true,
Running containers without a memory limit means the OOM killer might target something on the host instead if memory runs out. Setting limits isn’t just good practice for fairness, it’s about containing the blast radius.
cgroups v1 scattered resources across separate hierarchies, one tree for memory, another for CPU, another for block I/O. cgroups v2 unified everything under a single hierarchy. Most distributions have switched to v2 by now, so the paths look different from what you might see in older documentation, but the concepts are the same.
Container networking
Each container appears to have its own network interface and its own IP. There’s no hardware virtualization involved. So what’s actually going on?
The answer is virtual ethernet pairs, veth pairs. When Docker creates a container, the kernel creates two linked virtual interfaces. Think of them as two ends of a pipe. One end goes into the container’s network namespace and shows up as eth0. The other end stays on the host and gets attached to a bridge interface, almost always docker0.
$> ip link show docker0
3: docker0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc noqueue state UP
    link/ether 02:42:a1:b3:c9:d2 brd ff:ff:ff:ff:ff:ff
inet 172.17.0.1/16 brd 172.17.255.255 scope global docker0$> ip link show type veth
5: veth3a1b2c@if4: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 ...Traffic leaving the container goes through the veth pair into the bridge, then through the host’s network stack. Docker maintains iptables rules to handle the NAT:
$> iptables -t nat -L POSTROUTING
MASQUERADE  all  --  172.17.0.0/16  !172.17.0.0/16  anywhere
That MASQUERADE rule is what lets containers reach the internet. Outgoing packets from any container in the 172.17.0.0/16 range get their source IP rewritten to the host’s IP before leaving. From the outside, it looks like the host made the request.
Port publishing works in reverse. When you do -p 8080:80, Docker adds a DNAT rule:
$> iptables -t nat -L DOCKER
DNAT  tcp  --  anywhere  anywhere  tcp dpt:8080 to:172.17.0.2:80
Incoming packets on port 8080 get their destination rewritten to the container’s internal IP on port 80. The packet never actually leaves and re-enters the host, the kernel handles the rewrite in the network stack before it even reaches a socket.
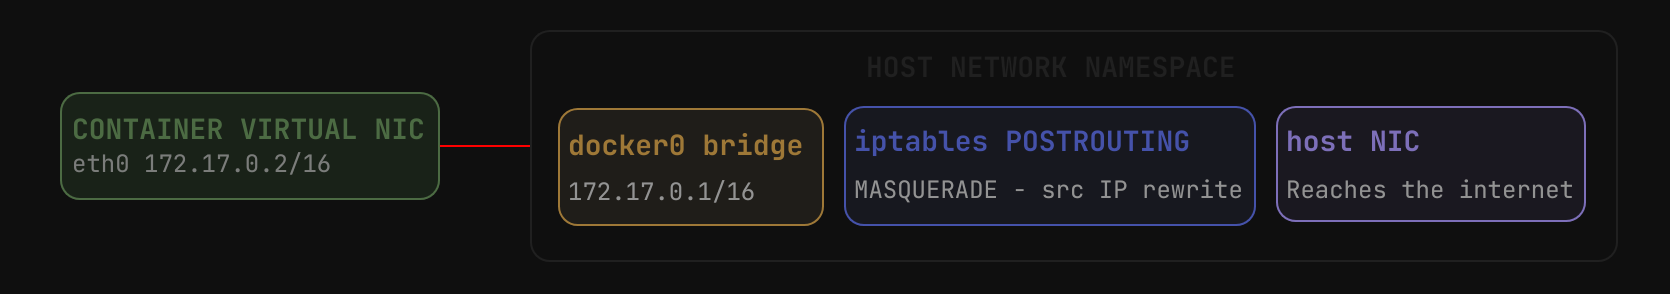
Packet path from container to the internet, veth pair, bridge, iptables NAT
--network host skips all of this entirely. The container shares the host’s network namespace directly. No bridge, no veth, no NAT. You’d reach for this when the overhead matters or when you need to bind to a specific host interface. The tradeoff is you give up network isolation completely.
OverlayFS
Every Docker image is made up of layers. When you pull an image, you’re pulling a stack of read-only filesystem snapshots. When you run a container from that image, Docker adds one thin writable layer on top. OverlayFS is what stitches all of that into a single coherent view.
It takes four things:
- lowerdir, the read-only image layers, stacked (there can be many)
- upperdir, the writable container layer
- workdir, a scratch directory the kernel uses internally
- merged, the final unified view the container actually sees
$> mount | grep overlay
overlay on /var/lib/docker/overlay2/<hash>/merged type overlay (rw,
lowerdir=<hash-n>/diff:...:<hash-1>/diff,
upperdir=<hash>/diff,
workdir=<hash>/work)
When the container reads a file, the kernel checks upperdir first. If it’s not there, it falls through the lowerdir stack. When the container writes to a file that only exists in lowerdir, the kernel performs a copy-on-write, copies the file up into upperdir, then applies the write there. The original in lowerdir is never touched.
$> docker history nginx
IMAGE          CREATED        CREATED BY                                      SIZE
a6bd71b11e68   2 weeks ago    CMD ["nginx" "-g" "daemon off;"]                0B
<missing>      2 weeks ago    EXPOSE map[80/tcp:{}]                           0B
<missing>      2 weeks ago    COPY /docker-entrypoint.d/ ...                  8.16kB
<missing>      2 weeks ago    RUN /bin/sh -c set -x && ...                    91.6MB
Each line is a layer. The 0B layers are metadata only, they don’t add a directory to the overlay stack.
The practical upside: ten containers running the same nginx image share the exact same lowerdir layers on disk. Only their respective upperdirs differ, containing only whatever changed at runtime. Image storage is far more efficient than it would be if each container had a full copy.
The practical downside: writing large amounts of data inside a container at runtime is expensive. Every write to a file that exists in lowerdir triggers a copy-on-write. For heavy disk I/O workloads, you want a volume mount that bypasses OverlayFS entirely and writes directly to the host filesystem:
$> docker run -v /data:/var/lib/data nginxAnything mounted as a volume is outside the overlay stack. Reads and writes go straight to the host path.
That covers the core of what’s actually running under a container. Namespaces give it isolation, cgroups set the resource boundaries, veth pairs and iptables wire up the network, and OverlayFS builds a layered filesystem out of static image snapshots. Docker itself is mostly a clean API sitting on top of all of this, the kernel is doing the real work.
Comments
You can write to me at [email protected]. Email services are insecure, consider encrypting emails with my PGP Key if you're sending me something sensitive.
Loading comments